
Every conversation, not a sample
AvonAI reads every conversation your agents have and ranks the ones that went wrong by severity and frequency.
For banks, insurers and other regulated companies
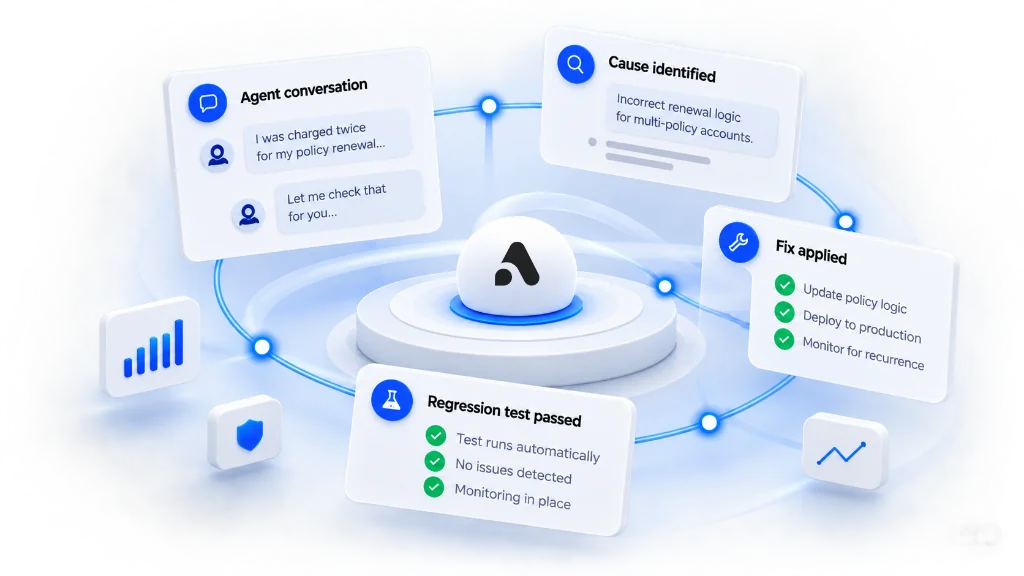
AvonAI reads every conversation your agents have and ranks the ones that went wrong by severity and frequency.
Each issue is traced to its cause, whether the data, a prompt, a guardrail or a tool, and fixed in the platform.
Every finding becomes a test that runs again whenever the agent, its model or its data changes.
The comparison
| Capability | AvonAI | Competitor 1Agent supervision | Competitor 2Compliance monitoring | Competitor 3AI evaluation | Competitor 4LLM engineering |
|---|---|---|---|---|---|
| Supervises agents from any builder: in-house, consultancy or vendor | |||||
| Made for the business teams that own the agent | |||||
| Business users define “correct” in plain language | |||||
| Checks answers against your policies and knowledge base | |||||
| Finds contradictions inside your knowledge base | |||||
| Traces each failure to its cause and fixes it in the platform | |||||
| Turns every finding into a test | |||||
| Reruns tests when the agent, model, data or vendor changes | |||||
| Built for regulated industries | Horizontal | Horizontal | Horizontal | ||
| Runs inside your perimeter, on your own model | By request | Self-host |
Competitor 1 to 4 are specific products in each category, unnamed here. Competitor capabilities are drawn from public websites, documentation and press as of September 2026. Products change, and unpublished features may exist. Not found means absent from public documentation, not proven absent.
See it on your own conversations.
Write to us at contact@avon-ai.com to set up a demo.